I/O vs ingress (split_io)
With receive and policy threads held fixed on
split_io, does adding
more I/O workers improve throughput when the upstream is slow
(forward_slow)?
Numbers are same-host comparisons on a single reference host and are not service-level objectives. See the performance hub disclaimer.
When this matters
On split_io,
ingress and async I/O are separate roles.
dataplane.io_workers sizes the I/O
pool that owns upstream wait; listener
threads stay the receive path.
This study asks whether adding I/O workers under
forward_slow moves QPS when
ingress/policy are fixed. See
worker counts
and dataplane runtime tuning.
What we varied
- Varied:
dataplane.io_workers(1,2,4,8) withdataplane.runtime:split_ioand fixed ingress (threads: 2) - Held fixed:
forward_slowload shape, observability off fixtures, same dnsperf recipe on a single reference host - Note:
io=2reuses the existing split_ioforward_slowscale cell
Evidence
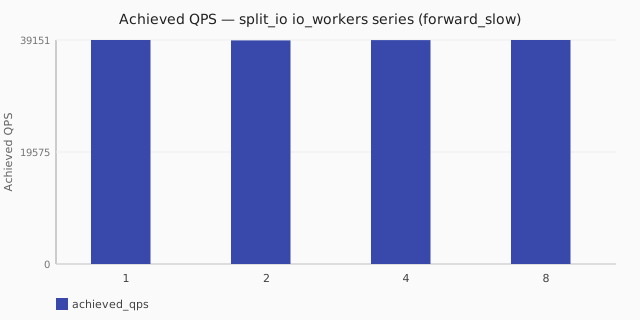
Achieved QPS — split_io io_workers series (forward_slow)
| I/O workers | Runtime | Achieved QPS | Avg latency (ms) | Sent | Completed | Lost | Workers |
|---|---|---|---|---|---|---|---|
| 1 | split_io | 39149.7 | 51.0 | 1176305 | 1176305 | 0 | ingress=2, policy=2, io=1 |
| 2 | split_io | 39080.2 | 51.1 | 1174342 | 1174342 | 0 | ingress=2, policy=2, io=2 |
| 4 | split_io | 39132.2 | 51.0 | 1175628 | 1175628 | 0 | ingress=2, policy=2, io=4 |
| 8 | split_io | 39150.6 | 51.0 | 1176530 | 1176530 | 0 | ingress=2, policy=2, io=8 |
At a glance
- split_io io_workers series (forward_slow):
2costs about 0% QPS versus1(~39k vs ~39k);4costs about 0% QPS versus1(~39k vs ~39k);8is about 1.0×1(~39k vs ~39k).
Takeaway
Adding I/O workers did not raise QPS under this slow-upstream recipe. With
ingress and policy fixed on
split_io, the
forward_slow series stays flat at
about ~39k QPS from io_workers 1 through 8 on this median — consistent
with the loadgen outstanding window and the slow-upstream recipe delay, not
with I/O thread starvation.
What to do: size io_workers for concurrency headroom and loss behavior on
your hardware (--study io-vs-ingress-split), not from this shape’s QPS
ceiling. For runtime choice and ingress sizing, see
sync vs split_io and
ingress concurrency (sync).
Related guides
- Runtime and concurrency — split_io model and worker roles
- Dataplane runtime tuning
- Reference: dataplane —
runtime,io_workers,policy_workers - Reference: listeners — ingress
threads - Ingress concurrency (sync)
- Sync vs split_io